IT AMC vs Managed Services vs Staff Augmentation: Choosing a Support Model

Three terms get used almost interchangeably when enterprises discuss IT support in India: AMC, managed services, and staff augmentation. They aren’t the same thing, and confusing them leads to mismatched contracts, where an organization signs up for hardware maintenance when what it actually needed was continuous infrastructure management, or pays for broad ongoing management when a straightforward repair contract would have covered the actual need at lower cost.

This guide compares AMC vs managed services vs staff augmentation: what each model actually covers, how they differ in scope, pricing and accountability, and how to decide which one, or which combination, fits your organization.

Key Takeaways

  • An AMC (Annual Maintenance Contract) is typically scoped around specific hardware or equipment, covering scheduled maintenance and break-fix support within a defined period.
  • Managed services cover a broader, continuous scope (proactive monitoring, patching, security and lifecycle management), not just reactive fixes when something breaks.
  • Staff augmentation adds skilled personnel to your team for a defined period or project, without an ongoing management relationship attached.
  • Comprehensive AMCs include parts and labor together; non-comprehensive AMCs typically cover labor only, with parts billed separately.
  • Outcome-based SLAs shift accountability from “how many visits or hours were delivered” to “was the agreed uptime or resolution target actually met,” which is a meaningfully different way to structure a contract.

What Is an IT AMC?

An Annual Maintenance Contract (AMC) is a fixed-term agreement, usually a year, covering the maintenance and repair of specific IT hardware or equipment: servers, network devices, printers, or end-user devices. It’s typically scoped around what breaks and needs fixing, scheduled preventive maintenance, and defined response times when hardware needs attention. It’s one of the oldest and most familiar support structures in the Indian enterprise IT market, and remains widely used precisely because it’s easy to scope and budget against.

AMCs come in two common structures, and the difference matters more than it might first appear.

Comprehensive AMC Non-Comprehensive AMC
What’s included Labor and parts/spares both covered under the contract Labor covered; parts and spares billed separately
Cost predictability Higher upfront cost, but fewer unexpected expenses Lower upfront cost, but variable cost when parts are needed
Best suited for Critical equipment where downtime cost outweighs the premium Lower-risk equipment, or organizations comfortable managing variable repair costs
Typical use case Servers, network core infrastructure Printers, peripherals, non-critical devices

Neither structure is inherently better. A comprehensive AMC makes sense for infrastructure where an unplanned parts cost could be significant or where budget predictability matters more than a lower headline price. A non-comprehensive AMC can be more cost-effective for equipment that rarely needs part replacement, as long as the organization is comfortable with occasional variable costs.

What Are Managed Services?

Managed IT services cover ongoing, proactive IT infrastructure management, not just fixing hardware when it fails. This typically includes continuous monitoring, patch management, security oversight, performance optimization, and support across servers, networks, endpoints and cloud environments, delivered under a defined SLA rather than a fixed annual maintenance scope.

The core difference from an AMC is proactive versus reactive. An AMC exists to fix what breaks within its defined scope. Managed services exist to reduce how often things break in the first place, catching degrading performance or emerging issues before they become failures, while also handling the reactive support work when something does go wrong. The pricing reflects this difference too: managed services are usually priced per device, per user, or as a broader subscription tied to the scope of coverage, rather than a flat annual figure per piece of hardware.

What Is Staff Augmentation?

Staff augmentation means bringing in external, skilled personnel to work as an extension of your internal team, typically for a defined project or period, without the ongoing management relationship that comes with a managed services contract. It’s a way to add capacity or specific expertise, such as a specialist for a migration project, without a long-term operational commitment attached.

Staff augmentation works well for temporary capacity gaps or specialized, time-bound initiatives. It’s not designed to replace ongoing infrastructure management or support, since the relationship typically ends when the project or contract period does.

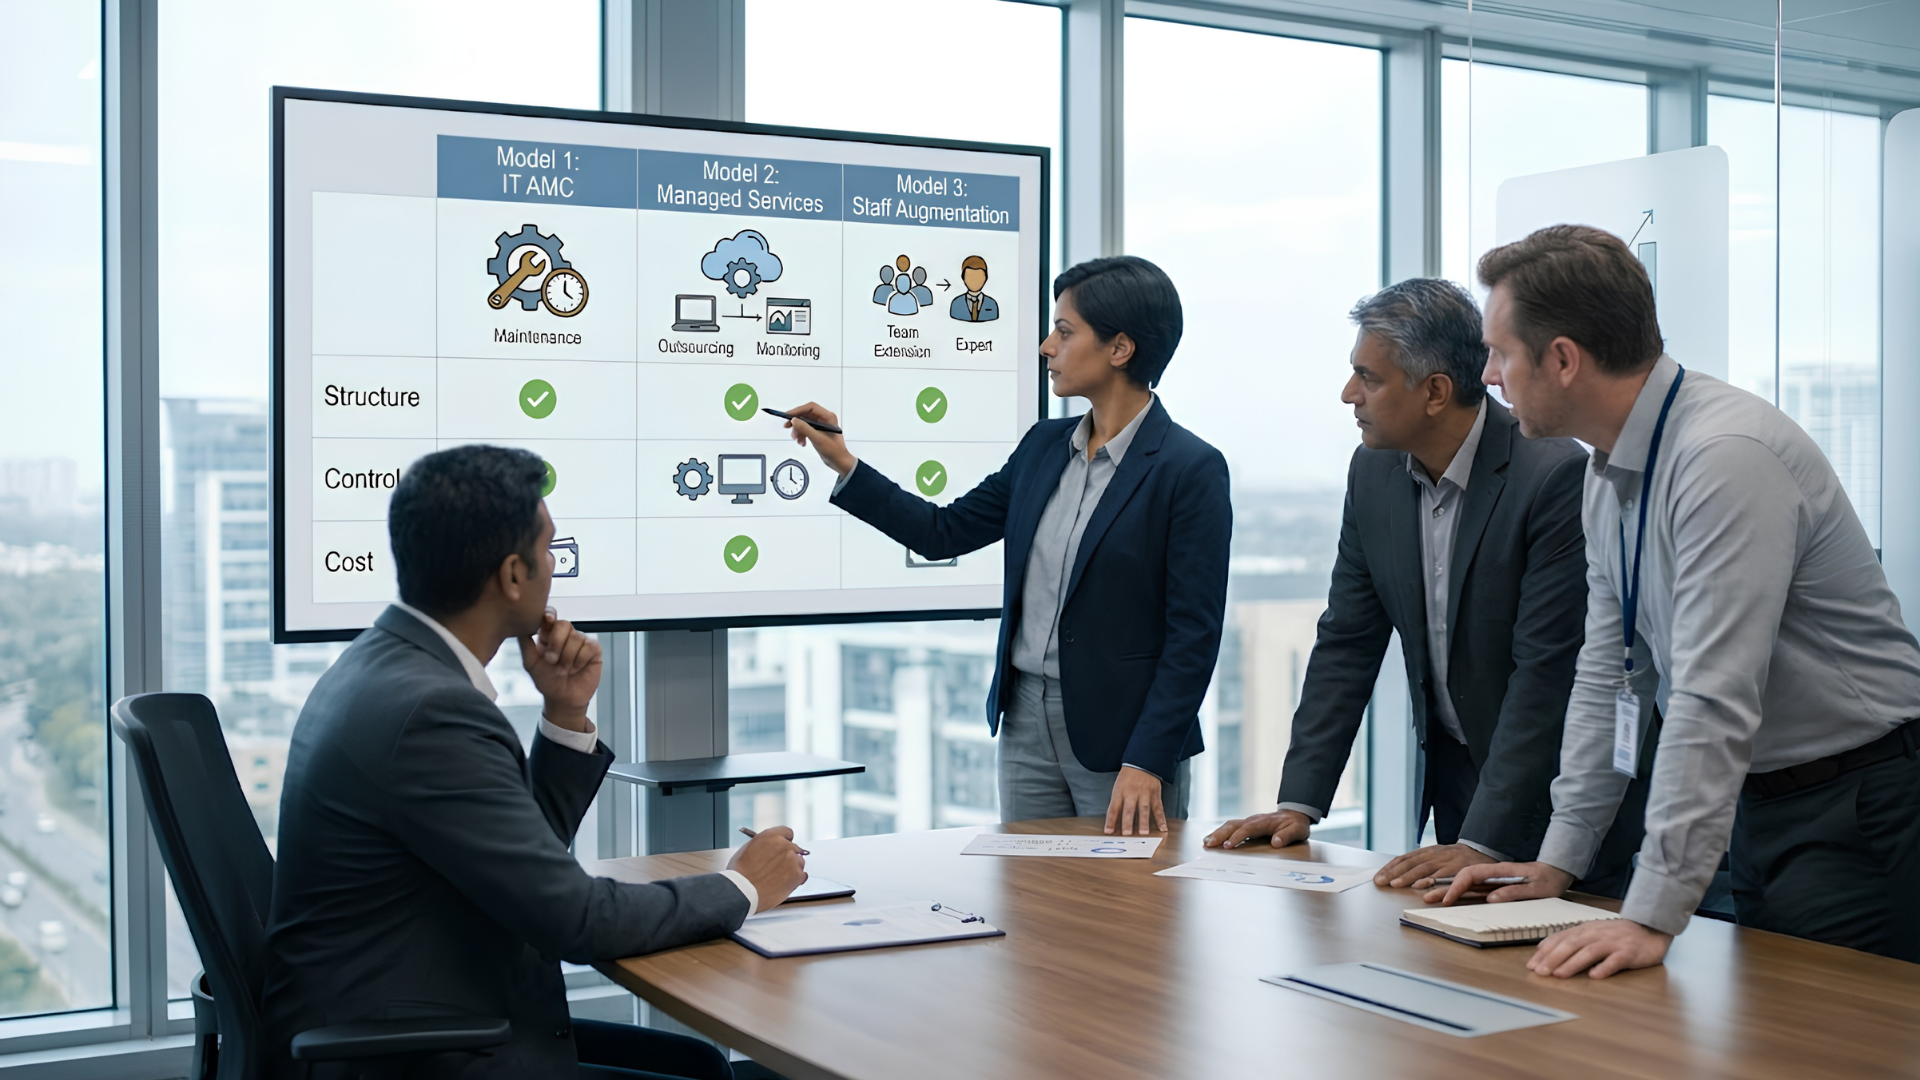
Comparing the Three Models

AMC Managed Services Staff Augmentation
Scope Specific hardware/equipment maintenance Broad, continuous infrastructure management Skilled personnel for a defined period or project
Approach Reactive, break-fix, with scheduled maintenance Proactive, continuous Task or project execution
Typical duration Usually one year, renewable Ongoing, often multi-year Defined project timeline
Pricing structure Fixed annual fee, sometimes with parts billed separately Subscription or per-device/per-user pricing tied to SLA Time-based or project-based rates
Best suited for Defined equipment needing scheduled upkeep and repair coverage Organizations wanting continuous oversight and reduced downtime risk Temporary capacity or specialized project needs

In practice, many enterprises use more than one of these models at once. Core servers might sit under a comprehensive AMC for guaranteed parts coverage, day-to-day infrastructure operations might run under a managed services agreement, and a specific migration project might bring in augmented staff for a few months. The models aren’t mutually exclusive; they solve different problems.

AMC vs Managed Services: Why the Distinction Matters

The confusion between these two terms causes real problems when it isn’t resolved before signing a contract. An organization expecting proactive monitoring and issue prevention, but that has only signed an AMC, will find that support only shows up once something has already failed. Conversely, an organization that only needs scheduled hardware maintenance may be paying for continuous management capabilities it doesn’t actually use.

Before choosing, it’s worth asking directly: are we trying to reduce the frequency of failures, or are we trying to make sure that when hardware does fail, it gets fixed quickly and predictably? The first points toward managed services. The second points toward a well-structured AMC.

Outcome-Based SLAs: A Different Way to Structure Accountability

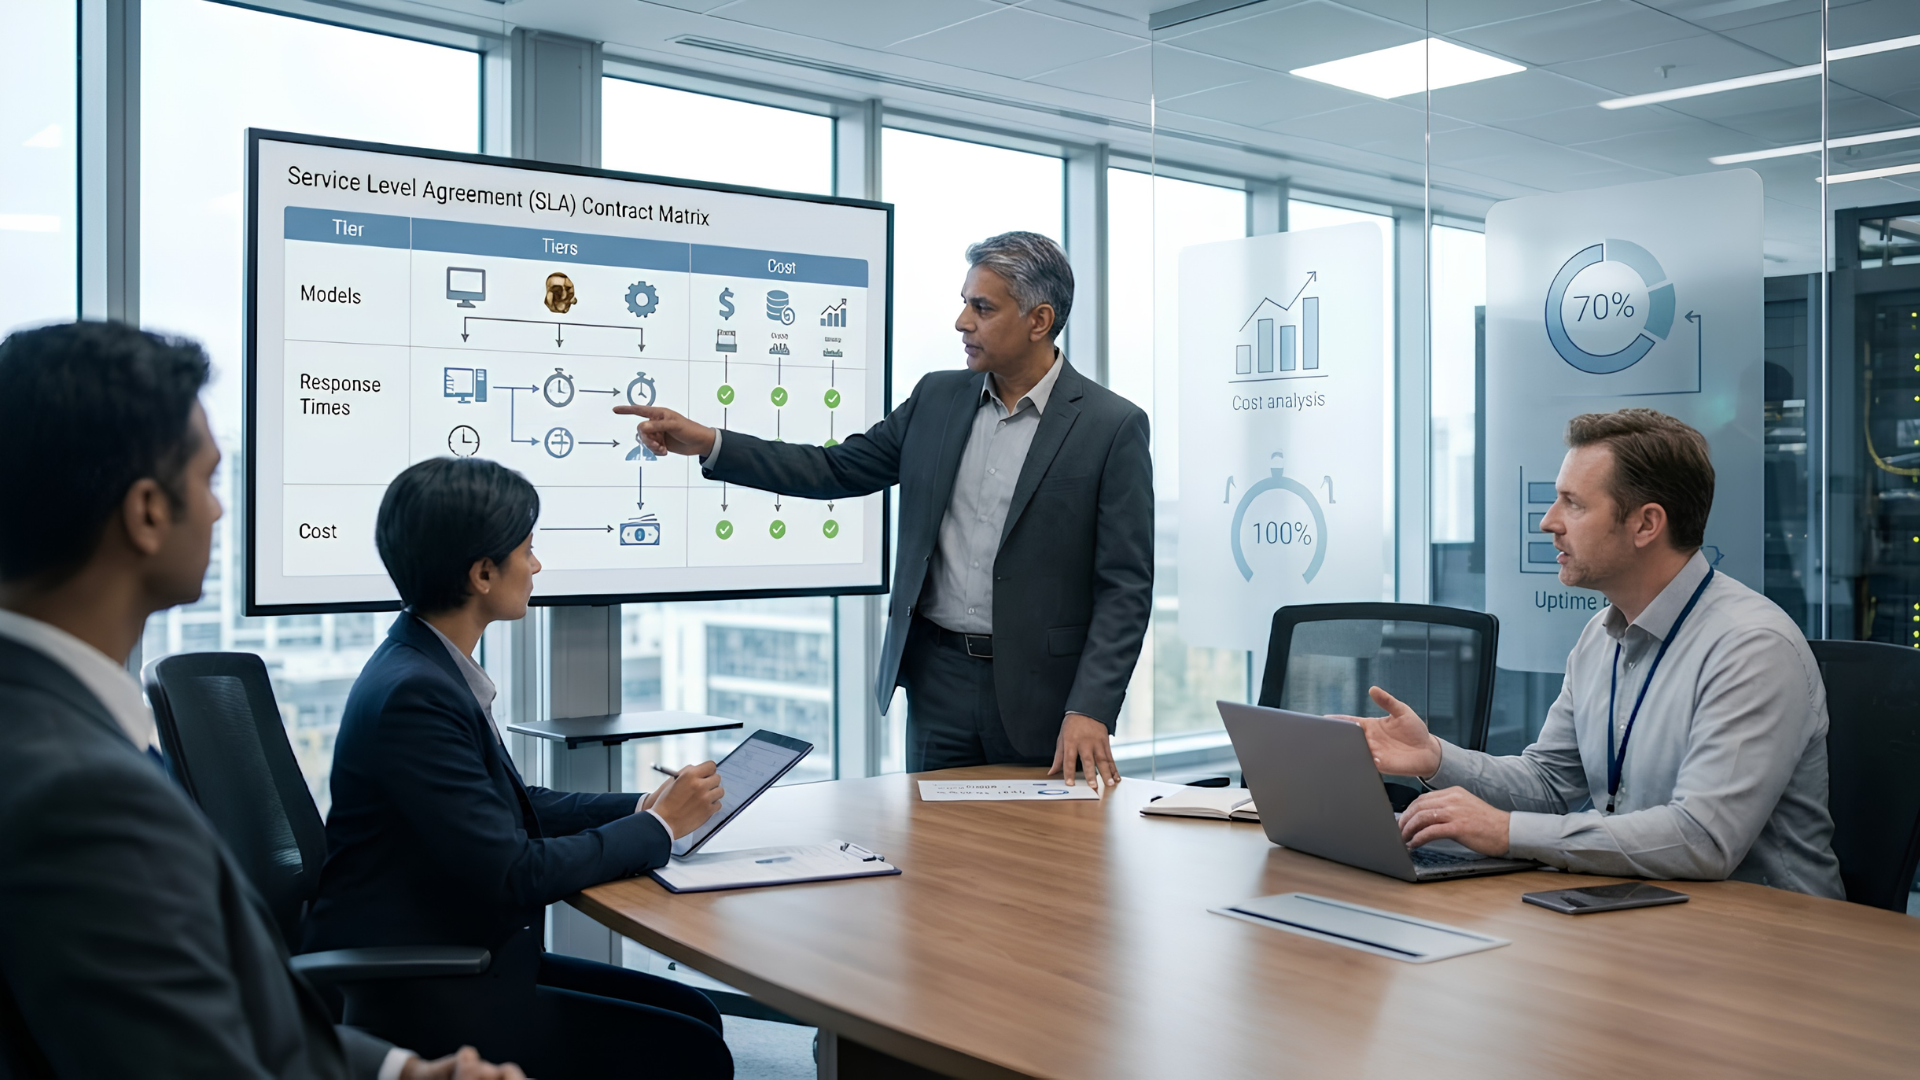
Traditional support agreements are often structured around inputs: number of site visits included, hours of coverage, or response time commitments. Outcome-based SLAs shift the focus to results: a guaranteed uptime percentage, a defined resolution time regardless of how many visits it takes to get there, or a specific first-time-fix rate.

This distinction matters because input-based agreements can technically be fulfilled while the actual outcome (minimal downtime, quick resolution) still falls short. Outcome-based SLAs tie the contract directly to what the business actually cares about, which is infrastructure staying available and issues getting resolved quickly, not simply that a technician showed up as scheduled.

When evaluating a managed services or AMC proposal from an IT infrastructure services company, it’s worth asking specifically whether the SLA is structured around outcomes or activities, since the two can look similar on paper but deliver very different accountability in practice.

How to Choose the Right Model

A few questions help clarify which model, or combination, fits your situation:

  1. Is the goal preventing failures or fixing them quickly when they happen? Managed services target prevention; AMCs target fast, predictable repair.
  2. How critical is the equipment or system involved? Higher-criticality infrastructure often justifies a comprehensive AMC or a managed services agreement with tighter SLAs, even at higher cost.
  3. Is this an ongoing need or a defined project? Ongoing operational needs point toward AMC or managed services; a time-bound initiative points toward staff augmentation.
  4. Do you have internal capacity to handle proactive monitoring yourself? If yes, a well-structured AMC for hardware coverage might be sufficient. If not, managed services fills that gap.
  5. Are current SLAs based on outcomes or activities? If you’re unsure, that’s worth clarifying before renewing an existing contract, not just when signing a new one.

Where Team Computers Fits In

Team Computers works with enterprises to structure the right combination of AMC, managed services and staff augmentation based on actual infrastructure needs, rather than defaulting to a single model regardless of fit. This includes advising on comprehensive versus non-comprehensive AMC coverage where it matters most, structuring managed services around outcome-based SLAs rather than vague activity commitments, and bringing in specialized capacity for specific projects when that’s genuinely what’s needed instead of a longer-term contract.

If your current support arrangement isn’t clearly mapped to what your organization actually needs, whether that’s proactive management, predictable hardware repair, or short-term project capacity, that mismatch is worth resolving before your next renewal.

Related reading

Frequently Asked Questions

What is the difference between AMC and managed services?

An AMC is typically scoped around maintaining and repairing specific hardware, with a reactive, break-fix approach and scheduled maintenance visits. Managed services cover broader, continuous, proactive management of infrastructure, including monitoring and issue prevention, not just fixing hardware after it fails.

What is the difference between comprehensive and non-comprehensive AMC?

A comprehensive AMC includes both labor and parts or spares within the contract cost, offering more predictable budgeting. A non-comprehensive AMC covers labor only, with parts billed separately as needed, resulting in a lower upfront cost but variable expenses when hardware components need replacement.

What is staff augmentation and how is it different from managed services?

Staff augmentation adds skilled personnel to your team for a defined project or period, functioning as extra capacity or expertise without an ongoing management relationship. Managed services involve continuous, proactive management of infrastructure under an ongoing contract, rather than temporary personnel support.

What is an outcome-based SLA?

An outcome-based SLA ties contract accountability to actual results, such as guaranteed uptime percentage or resolution time, rather than simply the number of visits or hours of coverage delivered. It focuses on whether the agreed business outcome was achieved, not just whether the activities were technically performed.

Can an organization use AMC, managed services and staff augmentation together?

Yes, and many enterprises do. Critical hardware might sit under a comprehensive AMC, day-to-day infrastructure operations might run under a managed services agreement, and specific projects might use staff augmentation for temporary specialized capacity. The three models address different needs rather than competing with each other.
IT Infrastructure Security: A 12-Point Checklist for Enterprise IT

Most infrastructure security failures aren’t caused by a single dramatic breach. They’re the result of smaller gaps left unaddressed for too long: an unpatched server, a flat network with no segmentation, an endpoint nobody hardened before deployment, a backup that was never actually tested. Individually, each gap looks minor. Together, they’re what attackers rely on.

This checklist covers twelve areas every enterprise should have a clear answer for when it comes to IT infrastructure security. It isn’t a compliance certification or an exhaustive technical standard. It’s a practical starting point for IT and security leaders to assess where their infrastructure stands, and where the real gaps are likely hiding, as part of a wider IT infrastructure management program.

Infrastructure security best practices tend to fall into a handful of categories: knowing what you have, limiting how far a compromise can spread, keeping systems current, controlling who can access what, and being ready to respond when prevention isn’t enough. The twelve points below map to those categories, roughly in the order most organizations find useful to work through them.

Key Takeaways

  • Infrastructure security is rarely about one big fix. It’s the sum of consistent practices across network design, endpoints, identity, data and monitoring.
  • Network segmentation and zero trust principles limit how far an attacker can move once they get past the first line of defense.
  • A documented patch management policy matters as much as the patching itself, since undocumented processes tend to quietly lapse.
  • Endpoint hardening and identity controls are often the highest-impact, lowest-cost improvements available to most organizations.
  • This checklist is meant to be used as a self-assessment, not a one-time audit. Security postures drift, and the strongest programs revisit these areas regularly.

1. Maintain a Complete, Current Asset Inventory

You can’t secure what you don’t know exists. Every component of your IT infrastructure, from servers and network devices to endpoints, cloud resources and applications, needs to be recorded somewhere, with a clear owner attached and its status kept current. Most enterprises carry more unrecorded infrastructure than they realize: a decommissioned server that was never actually powered off, a cloud instance spun up for a project and forgotten about, or a legacy device still connected to the network long after its intended retirement. Regular discovery scans, reconciled against the recorded inventory, close this gap before it becomes a quiet entry point for an attacker.

2. Apply Network Segmentation

A flat network, where every device can reach every other device by default, means a single compromised endpoint can potentially reach everything else on the network. Network segmentation divides infrastructure into smaller, isolated zones, so that a breach in one segment doesn’t automatically grant access to the rest. Critical systems, such as servers holding sensitive data or finance applications, should sit in more restricted segments than general user devices, with clearly defined rules governing what can talk to what and why. Guest and IoT devices, in particular, are worth isolating into their own segment, since they’re often the least monitored part of a network and a common entry point in real incidents.

3. Move Toward a Zero Trust Architecture

Traditional network security often assumes anything inside the perimeter can be trusted. Zero trust infrastructure works from the opposite assumption: no user, device or system is trusted by default, regardless of whether it’s inside or outside the network boundary. Every access request is verified based on identity, device health and context, not just network location. Moving to zero trust is usually a gradual shift rather than a single project, but even partial adoption, such as requiring continuous verification for access to sensitive systems, meaningfully reduces risk.

4. Enforce a Formal Patch Management Policy

Unpatched systems remain one of the most common ways attackers gain access, not because patches are unavailable, but because they aren’t applied consistently. A documented patch management policy should define how quickly critical vulnerabilities get patched, who’s responsible for testing and deploying patches, and how exceptions are tracked and reviewed rather than quietly ignored. Without a written policy, patching tends to happen inconsistently, depending on whoever remembers to prioritize it that week. Once the policy is in place, routine patch deployment is also one of the first tasks worth handing to IT infrastructure automation.

5. Harden Endpoints Before and After Deployment

Endpoint hardening means configuring laptops, desktops and mobile devices to reduce their attack surface before they ever reach a user: disabling unnecessary services, enforcing disk encryption, restricting administrative privileges, and applying security baselines consistently across the fleet, usually backed by endpoint security tooling that enforces them. This matters as much for devices already in use as for new deployments, since hardening standards tend to slip over a device’s lifecycle unless they’re actively maintained.

6. Strengthen Identity and Access Management

Access should follow the principle of least privilege: users and systems get only the access they genuinely need for their role, not broad access granted “just in case” and never revisited. Multi-factor authentication should be standard for any access to sensitive systems, not treated as an optional extra reserved for a handful of accounts. Regular access reviews matter too, removing permissions that accumulated over time but are no longer needed, particularly for employees who’ve changed roles, moved teams, or left the organization entirely. Dormant accounts that were never deactivated are a surprisingly common finding in security reviews, and an easy one to fix once identified.

7. Encrypt Data at Rest and in Transit

Data should be encrypted both while it’s stored and while it’s moving across networks. This protects information even if a device is lost, a storage system is compromised, or network traffic is intercepted. Encryption is one of the more mature, well-understood security controls available, but it’s still common to find gaps: unencrypted backups, laptops without full-disk encryption, or internal traffic assumed to be safe simply because it never leaves the corporate network.

8. Centralize Logging and Continuous Monitoring

Security events scattered across disconnected systems are much harder to detect than events visible in one centralized view. Centralized logging, paired with continuous monitoring, helps identify unusual patterns, such as repeated failed logins or unexpected configuration changes, before they escalate into a larger incident. The goal isn’t just collecting logs, but actively reviewing them, since unmonitored logs provide evidence after an incident rather than warning before one.

9. Run Regular Vulnerability Assessments

Infrastructure changes constantly: new devices get added, configurations get updated, software gets installed. Regular vulnerability assessments identify weaknesses introduced by these changes before they’re exploited, rather than relying on a single annual audit to catch everything. Findings should feed directly into the patch management process, with clear ownership for remediation and a defined timeline based on severity.

10. Maintain Tested Backup and Disaster Recovery Plans

Backups that have never been tested are a common and costly assumption to make. A backup strategy needs regular restoration testing to confirm data can actually be recovered within an acceptable timeframe, not just that a backup job completed successfully overnight. Disaster recovery planning should account for realistic scenarios beyond hardware failure, including ransomware incidents where backups themselves may be targeted or encrypted alongside production data. Recovery time and recovery point objectives should be defined clearly, agreed with the business, and reflected honestly in what the current setup can actually deliver, rather than what leadership assumes it can.

11. Secure Physical Infrastructure and Facilities

Digital controls matter less if physical access to servers, network equipment or data centers isn’t controlled. Server rooms and equipment closets should have restricted access, monitored entry, and environmental controls in place. This extends to end-user devices too: physical security policies, device tracking and secure disposal processes for retired hardware all reduce the risk of data exposure through a channel that’s easy to overlook amid digital security priorities.

12. Have an Incident Response Plan Ready

Even strong preventive controls don’t eliminate risk entirely, which makes a tested incident response plan essential. This should define clear roles and responsibilities, communication protocols during an incident, and step-by-step containment and recovery procedures, reviewed and practiced before they’re actually needed. An incident response plan that only exists as a document, never rehearsed, tends to fall apart under the pressure of an actual incident.

How to Use This Checklist

Treat this less as a one-time audit and more as a recurring self-assessment. Go through each of the twelve areas, rate your current state honestly, whether that’s not started, partially in place, or fully mature, and prioritize the gaps most likely to be exploited first. Network segmentation, patch management and identity controls are usually the highest-leverage places to start, since they address common, well-understood attack paths rather than edge cases.

Security posture also isn’t static. New devices get added, configurations drift, and threats evolve, which means this checklist works best as a recurring review rather than a box checked once and filed away.

Where an Experienced Technology Partner Helps

Working through a checklist like this is straightforward in concept, but maintaining consistent security practices across a growing device fleet, distributed offices and evolving infrastructure takes sustained operational effort. This is exactly where an experienced technology partner adds practical value: helping run a cyber security assessment against these areas, hardening and standardizing device configurations at scale, and building the ongoing monitoring and patch management discipline that keeps security from quietly slipping between reviews.

If it’s been a while since your organization worked through an infrastructure security assessment, that’s a reasonable place to start the conversation, before a gap turns into an incident.

Related reading

Frequently Asked Questions

What is IT infrastructure security?

IT infrastructure security refers to the practices, policies and controls used to protect an organization's servers, networks, endpoints, data and facilities from unauthorized access, misuse or compromise. It spans everything from network design and identity controls to physical security and incident response.

What is network segmentation and why does it matter?

Network segmentation divides a network into smaller, isolated zones so that a breach in one area doesn't automatically grant access to the rest of the infrastructure. It limits how far an attacker can move after gaining initial access, making it one of the more effective controls for containing a security incident.

What does zero trust infrastructure actually mean?

Zero trust is a security model that assumes no user, device or system should be trusted by default, regardless of whether it's inside or outside the network perimeter. Every access request is verified based on identity, device health and context, rather than relying on network location alone.

Why does patch management need a formal policy rather than just regular patching?

A documented policy defines how quickly vulnerabilities of different severities get patched, who's responsible, and how exceptions are tracked. Without this, patching tends to happen inconsistently, dependent on individual initiative rather than a consistent, accountable process.

What is endpoint hardening?

Endpoint hardening is the practice of configuring devices, such as laptops and desktops, to reduce their attack surface before and during use. This includes disabling unnecessary services, enforcing encryption, restricting administrative privileges, and applying consistent security baselines across the device fleet.

IT Infrastructure Automation: Where to Start and What to Automate First

Most IT teams don’t lack automation because the tools aren’t available. They lack it because nobody’s mapped out what to automate first, so ambitious plans stall before anything ships, or automation gets applied to low-value tasks while the genuinely repetitive, error-prone work stays manual. The result is often a patchwork: a few scripts here, a handful of scheduled jobs there, without a coherent path toward a more automated environment.

This guide walks through how to approach IT infrastructure automation practically: what it actually covers, how to decide what to automate first, and a step-by-step path from manual operations to a more automated environment, without needing to overhaul everything at once.

Key Takeaways

  • IT infrastructure automation replaces manual, repetitive tasks, such as provisioning, patching and incident response, with scripted or policy-driven processes.
  • The right starting point isn’t a tool decision. It’s an honest audit of which manual tasks are frequent, repetitive and error-prone enough to justify automating first.
  • Infrastructure as code, automated provisioning and runbook automation are the three building blocks most organizations should tackle before layering in more advanced capabilities like AIOps.
  • Starting small and expanding gradually produces better long-term outcomes than attempting to automate an entire environment at once.
  • Automation still needs governance. Poorly tested automated processes can scale mistakes just as efficiently as they scale good outcomes.

What Is IT Infrastructure Automation?

IT infrastructure automation is the use of scripts, tools and policy-driven processes to carry out infrastructure tasks that would otherwise require manual, repetitive human effort: provisioning a new server, deploying a patch across hundreds of devices, restarting a failed service, or onboarding a new employee’s accounts and access.

It spans a wide range of maturity. At the simple end, a script that automates a single repetitive task. At the more advanced end, infrastructure as code managing entire environments, and AI-driven systems detecting and resolving issues with minimal human involvement. Most organizations sit somewhere in between, with a mix of manual and automated processes across different parts of their infrastructure.

The goal isn’t automation for its own sake. It’s reducing the time IT teams spend on repetitive work, reducing the human error that comes with manual, repeated tasks, and freeing capacity for the work that actually needs human judgment, which is the same aim as any well-run IT infrastructure management program.

Why Prioritization Matters More Than Tool Selection

A common mistake is starting with the question “which automation platform should we buy,” before answering a more fundamental one: “which of our manual tasks are actually worth automating first.” Without that groundwork, automation efforts tend to either stall entirely or get applied to tasks that don’t move the needle.

A simple way to evaluate candidates is to weigh four factors for each manual process currently in place:

Frequency. How often is this task performed? A task done daily or weekly is a stronger automation candidate than one done rarely.

Time cost. How much cumulative time does this task consume across the team, not just per instance?

Error risk. How often do mistakes happen when this task is done manually, and how costly are those mistakes when they occur?

Standardization potential. Can this task be defined with clear, repeatable rules, or does it genuinely require judgment and context that varies each time?

Tasks that score high on frequency, time cost and error risk, with genuine standardization potential, are the strongest candidates to automate first. Tasks requiring nuanced judgment, or performed rarely enough that building automation costs more than the manual effort it saves, are usually better left alone, at least initially.

Where to Start: A Step-by-Step Approach

Step 1: Audit Your Manual, Repetitive Tasks

Before automating anything, build a clear list of what your IT team actually spends time on repeatedly. This often surfaces surprises: tasks nobody realized were consuming as much time as they were, or steps that had become manual workarounds for something that should have been standardized long ago. Involve the people actually doing the work, since they typically have the clearest view of where time genuinely goes.

Step 2: Rank Candidates Using Impact and Effort

Score each identified task against the frequency, time cost, error risk and standardization criteria above, then weigh that against how difficult each would be to actually automate. The best starting points are high-impact tasks that are also relatively straightforward to automate, not necessarily the tasks causing the most visible pain if they’re also the hardest to solve first.

Step 3: Start with Automated Provisioning

Automated provisioning, the process of setting up new servers, devices, user accounts or environments through predefined scripts or templates rather than manual configuration, is one of the highest-value starting points for most organizations. It’s typically well-defined, performed frequently, and prone to inconsistency when done manually, such as a new server missing a security setting that others in the same environment have.

Starting here also builds team confidence and experience with automation before moving into more complex territory, since provisioning tasks tend to have clear, testable success criteria. For large laptop and desktop rollouts, these device deployment automation techniques are a good place to start.

Step 4: Introduce Infrastructure as Code

Infrastructure as code (IaC) means defining and managing infrastructure (servers, networks, configurations) through code and version-controlled files, rather than manual setup through a console or interface. Once defined as code, infrastructure becomes reproducible, auditable, and far less prone to the “it works on this server but not that one” inconsistency that comes from manual configuration drifting apart over time as different technicians make different small adjustments without a shared record of what changed.

This is usually a natural progression after automated provisioning, since IaC essentially formalizes and version-controls the same underlying idea: defining infrastructure in a repeatable, testable way rather than configuring it by hand each time. It also makes disaster recovery meaningfully faster, since a documented, code-based definition of an environment can be redeployed far more quickly than manually rebuilding it from memory or scattered documentation after a failure.

Step 5: Build Runbook Automation for Common Incidents

Runbook automation takes documented incident response procedures, the manual steps a technician would normally follow to diagnose or resolve a known issue, and turns them into automated or semi-automated workflows. A classic example: a service that stops responding gets automatically restarted, with a notification sent only if the automated restart doesn’t resolve the issue.

Start with well-understood, frequently recurring incidents where the resolution steps are already clearly documented and consistent. Ambiguous incidents that genuinely require human diagnosis are poor candidates for full automation, though even partial automation, such as automatically gathering diagnostic information before a human gets involved, can meaningfully reduce resolution time and take routine work off the L1 support desk.

Step 6: Layer in Monitoring-Driven Automation

Once the fundamentals are in place, IT infrastructure monitoring systems can trigger automated responses directly: scaling resources automatically when demand increases, or triggering a predefined remediation workflow when a specific alert fires. This is where automation starts overlapping with AIOps, the use of AI and machine learning to analyze infrastructure data and support or automate operational decisions.

AIOps adoption in India has been growing alongside broader enterprise digital transformation, though it’s worth treating this as a later-stage capability rather than a starting point. Its effectiveness depends heavily on the quality of the underlying monitoring and automation already in place. Layering AIOps onto an environment with inconsistent monitoring or unreliable automation tends to amplify existing gaps rather than fix them.

Step 7: Build Governance Before Scaling Further

As automation expands, so does the consequence of something going wrong at scale. Establish testing procedures before any automated process runs in production, version control for scripts and configurations, and clear rollback procedures if an automated change causes an unintended issue. Governance isn’t a blocker to automation moving faster. It’s what allows automation to expand safely without a single bad script causing a much larger problem than the manual process it replaced ever could.

What to Automate First: A Practical Starting List

Based on the prioritization approach above, a few categories consistently make strong early candidates across most enterprise environments:

  • New device and server provisioning, using standardized templates rather than manual setup each time.
  • User onboarding and offboarding, particularly account creation, access assignment, and access revocation when someone leaves.
  • Patch deployment, at least for well-tested, routine updates across standard device configurations, backed by the patch policy from our IT infrastructure security checklist.
  • Backup verification, automatically confirming backups completed successfully and flagging failures, rather than assuming success.
  • Routine alert triage, automatically gathering relevant diagnostic data when a common alert fires, before a technician gets involved.
  • Compliance and configuration reporting, automatically checking systems against required baselines rather than manual periodic audits.

These tend to be frequent, well-understood, and low-risk to automate, making them a sensible place to build early automation experience before tackling more complex or judgment-dependent processes.

Common Pitfalls When Starting Automation

A few patterns consistently derail automation efforts, worth watching for early:

Automating a broken process. Automation makes a process faster and more consistent, but it doesn’t fix a process that was poorly designed to begin with. Automating a flawed manual workflow just means mistakes happen faster and more consistently.

Skipping testing before production use. Automated scripts that haven’t been properly tested can cause damage at a speed and scale a manual process never could.

No clear ownership. Automated processes still need someone accountable for maintaining them as environments change, not just the person who originally built them.

Trying to automate everything at once. Ambitious, all-at-once automation projects tend to stall. Incremental automation, starting with a handful of high-value tasks and expanding gradually, produces more durable results.

Treating automation as a one-time project. Infrastructure changes over time, and automated processes need periodic review to stay accurate and useful, not just an initial build followed by years of assumption that it’s still working correctly.

Where an Experienced Technology Partner Helps

Automation done well requires more than scripting knowledge. It requires understanding which processes are genuinely worth automating, building automation with proper testing and governance from the start, and maintaining it as infrastructure evolves. Many internal IT teams have the technical capability to automate individual tasks but lack the bandwidth to build and maintain automation as a sustained practice alongside everything else they’re responsible for day to day.

This is where IT infrastructure automation services from an experienced partner add value: helping prioritize what to automate first based on your actual environment rather than a generic template, building automated provisioning and infrastructure as code practices correctly from the outset, and providing the ongoing discipline that keeps automation reliable rather than becoming one more system nobody fully understands a year later.

If manual, repetitive tasks are consuming more of your team’s time than they should, that’s usually a good signal it’s time to map out where automation could realistically help, starting with the highest-impact, lowest-risk candidates first.

Related reading

Frequently Asked Questions

What is IT infrastructure automation?

IT infrastructure automation is the use of scripts, tools and policy-driven processes to carry out infrastructure tasks, such as provisioning, patching and incident response, that would otherwise require repeated manual effort. It reduces time spent on routine work and lowers the risk of human error in repetitive processes.

What should I automate first?

Start with tasks that are frequent, time-consuming, prone to human error, and well-defined enough to standardize, such as server or device provisioning, user onboarding and offboarding, and routine patch deployment. These tend to offer the clearest early return with the lowest risk.

What is the difference between automated provisioning and infrastructure as code?

Automated provisioning uses scripts or templates to set up infrastructure, such as servers or user accounts, without manual configuration each time. Infrastructure as code goes further, defining entire infrastructure environments through version-controlled code, making configurations reproducible, auditable and easier to manage consistently at scale.

What is runbook automation?

Runbook automation converts documented incident response procedures into automated or semi-automated workflows, so common, well-understood issues can be diagnosed or resolved without requiring a technician to manually follow each step every time.

Is AIOps relevant for enterprises in India right now?

AIOps adoption is growing in India alongside broader digital transformation, but it works best as a later-stage capability built on top of reliable monitoring and automation fundamentals. Organizations without consistent monitoring or automation in place should generally focus on those fundamentals first, since AIOps tends to amplify existing gaps rather than resolve them on its own.

What Is IT Infrastructure? Components, Types and Real Examples

Ask five people in an organization “what is IT infrastructure?” and you’ll likely get five different answers: the servers, the internet connection, the laptops, “the cloud,” or simply “IT.” All of them are partly right, which is exactly why the term causes confusion. IT infrastructure isn’t one thing. It’s the combined set of hardware, software, networks and facilities an organization needs to run its technology, and every one of those pieces has to work together for the business to function.

This guide answers the most common questions IT and business leaders ask about IT infrastructure: what it means, what it’s made of, the different types it can take, and what it actually looks like inside a real organization.

Key Takeaways

  • IT infrastructure means the combined hardware, software, networking components and facilities an organization needs to build, run and support its IT services.
  • The core components of IT infrastructure fall into a few groups: hardware, software, network infrastructure, data storage, and the facilities/security layer around them.
  • IT network infrastructure specifically refers to the physical and virtual components (routers, switches, cabling, wireless access points and related protocols) that let devices and systems communicate with each other.
  • There are several types of IT infrastructure (traditional, converged, hyperconverged and cloud-based), and most enterprises today run some mix of them rather than a single type.
  • Real examples make the definition concrete: everything from the laptop an employee uses, to the Wi-Fi access point in a meeting room, to the cloud account running a company’s applications, is part of IT infrastructure.

What Is IT Infrastructure? (IT Infrastructure Meaning)

IT infrastructure means the underlying hardware, software and networking components an organization depends on to build, operate and support its technology environment. It covers everything from the physical equipment sitting in a server room to the operating systems and applications running on top of it, and the network connections that tie all of it together.

Put simply: IT infrastructure is the technology foundation everything else in a business runs on. Email, file storage, video calls, business applications, point-of-sale systems, remote work: none of it functions without an underlying infrastructure of devices, connections and systems working together in the background.

It’s worth separating this from a related but different idea: infrastructure is the technology itself, while IT operations or IT infrastructure management is the ongoing discipline of running, monitoring and improving that technology. An organization can own strong infrastructure and still manage it poorly, which is usually where the real problems start.

What Are the Components of IT Infrastructure?

IT infrastructure components are generally grouped into a few categories that work together as a system rather than in isolation.

1. Hardware

Hardware is the physical foundation, the equipment you can actually touch. It includes servers, data storage devices, networking equipment like routers and switches, and end-user devices such as laptops, desktops, tablets and mobile phones. The facilities that house and support this equipment (server rooms, data centers, and their power and cooling systems) are usually considered part of the hardware layer too.

2. Software

Software components are what let IT teams actually use and manage the hardware layer. This includes operating systems, database management systems, virtualization software, and the everyday business applications employees rely on. Middleware, the layer that lets different software applications communicate with one another, also falls into this category.

3. Network Infrastructure

IT network infrastructure is the physical and virtual layer that connects everything else: routers, switches, cabling, wireless access points, and the protocols and services that let devices exchange data. Without a functioning network layer, none of the other components can actually talk to each other, which is why network reliability is often the first thing people notice when infrastructure isn’t working well. It’s also why IT infrastructure monitoring usually tracks network health alongside servers and storage.

4. Data Storage

Storage systems organize and preserve an organization’s data, from structured databases to file storage and backup systems. This spans on-premises storage arrays as well as cloud-based storage services, and it has to account for both everyday access and long-term backup and recovery.

5. Facilities and Security

Physical facilities (data centers, server rooms, and the power, cooling and physical security systems that support them) are part of the infrastructure definition too, even though they’re easy to overlook. Layered across every component above is security infrastructure: firewalls, access controls, monitoring and identity management, which protect the other categories rather than standing apart from them.

What Are the Different Types of IT Infrastructure?

Not every organization builds infrastructure the same way. Broadly, there are four common approaches, and most enterprises today run some combination rather than picking just one.

Traditional Infrastructure

In a traditional setup, every component (servers, storage, networking) is purchased, configured and managed separately. This gives an organization maximum flexibility and control over each individual piece, but it also means more integration work and more moving parts for the IT team to manage on its own.

Converged Infrastructure

Converged infrastructure bundles the same core components (servers, storage and networking) into a single, pre-integrated system, rather than assembling them piece by piece from different vendors. It’s largely the same underlying technology as traditional infrastructure, just packaged in a way that’s simpler to purchase, deploy and support.

Hyperconverged Infrastructure (HCI)

Hyperconverged infrastructure takes this a step further, using software to combine compute, storage and networking into a single unified system that functions as one rather than as separate parts. This software-defined approach simplifies deployment and scaling, which is one reason it has become a popular choice for use cases like virtual desktops and smaller edge locations.

Cloud Infrastructure

Cloud infrastructure runs on virtualized resources hosted by a cloud provider rather than on equipment an organization owns and maintains itself. It can be consumed in different forms: infrastructure delivered as a service is the closest equivalent to owning physical hardware, with platform and software layers often built on top of it.

Most organizations today aren’t purely one type. A typical enterprise might run core applications on hyperconverged infrastructure in a data center, host some workloads in the cloud, and still manage a traditional network and device fleet at branch locations, which is exactly why “hybrid” has become less a specific technology choice and more the default operating reality for most IT teams.

Real Examples of IT Infrastructure

Definitions are useful, but IT infrastructure is easier to understand through what it actually looks like day to day. A few concrete examples, spanning the components covered above:

  • A company’s Wi-Fi network: the wireless access points, switches and cabling that let every device in the office connect to the internet and internal systems.
  • The laptops and desktops employees use every day: end-user hardware running an operating system, security software and the applications people need to do their jobs.
  • A file server or cloud storage account: where shared documents, project files and business data live and are backed up.
  • A company’s email and collaboration platform: software infrastructure that depends on underlying servers, storage and network connectivity to function reliably.
  • The firewall and VPN protecting a corporate network: the security layer sitting across hardware and network infrastructure to keep unauthorized traffic out.
  • A retail store’s point-of-sale system: a combination of hardware (the terminal), software (the transaction application), and network infrastructure (the connection back to inventory and payment systems).
  • A video conferencing setup in a meeting room: collaboration hardware (camera, speaker, display) connected to software and network infrastructure that makes remote meetings possible.

Each example touches more than one component category, which is the core idea worth taking away: IT infrastructure isn’t a single system to point at. It’s the combination of many systems that only deliver value when they’re working together.

Where This Fits Into a Broader Technology Strategy

Understanding what IT infrastructure is made of is the starting point, but most organizations don’t struggle with the definition. They struggle with keeping every component current, secure and aligned as the business grows: devices reaching end of life at different times, network capacity not keeping pace with headcount, or fragmented purchasing decisions across hardware, software and cloud that were never planned as one connected system.

This is where having an experienced technology partner involved makes a practical difference: helping an organization evaluate the right IT infrastructure solutions across hardware and OEM options, plan deployment at scale, and manage the lifecycle of that infrastructure rather than treating each purchase as a one-off. If your organization is mapping out its infrastructure strategy for the year ahead, that’s a conversation worth having with your technology partner early, not after a gap turns into a problem.

Related reading

Frequently Asked Questions

What does IT infrastructure mean in simple terms?

IT infrastructure means all the hardware, software, networking components and facilities an organization needs to run its technology and deliver its IT services, from the physical devices people use, to the network connecting them, to the software running on top.

What are the main components of IT infrastructure?

The main components of IT infrastructure are hardware (servers, storage, networking equipment, end-user devices), software (operating systems, databases, applications), network infrastructure (routers, switches, wireless access), data storage, and the facilities and security systems that support all of the above.

Is IT infrastructure the same as IT network infrastructure?

No. IT network infrastructure is one part of the broader IT infrastructure: specifically, the routers, switches, cabling, wireless access points and protocols that connect devices and systems. IT infrastructure is the larger category that also includes hardware, software, storage and facilities beyond the network layer.

What is an example of IT infrastructure in a business?

Common examples include a company's office Wi-Fi network, employee laptops and desktops, a file server or cloud storage system, the email and collaboration platform staff use, and the firewall protecting the corporate network. Each is a piece of a larger, connected infrastructure rather than a standalone system.

What's the difference between traditional and cloud IT infrastructure?

Traditional infrastructure is hardware an organization purchases, hosts and manages itself: servers, storage and networking equipment typically kept in an on-premises server room or data center. Cloud infrastructure runs on virtualized resources hosted and maintained by a cloud provider, which an organization accesses remotely rather than owning outright. Most enterprises today run a hybrid mix of both rather than choosing exclusively one or the other.

Why does understanding IT infrastructure matter for a business, not just IT teams?

Because nearly every business function (communication, data storage, customer service, transactions) depends on infrastructure working reliably behind the scenes. When infrastructure decisions are made piecemeal, without a clear view of how components fit together, the business ends up absorbing the cost later through downtime, security gaps, or technology that doesn't scale with growth.

IT Infrastructure Monitoring: Metrics, Tools and Setup Guide

Most IT teams don’t find out about a failing server from a monitoring alert. They find out from an employee complaint, a stalled transaction, or a customer support ticket. By the time that happens, the problem has usually been building for hours or days. IT infrastructure monitoring exists to close that gap: to catch degrading performance, capacity limits and failing components before they turn into outages users actually notice.

This guide walks through what IT infrastructure monitoring covers, the metrics worth tracking, how monitoring differs from observability, and a practical step-by-step approach to setting it up, whether you’re building a monitoring program from scratch or fixing gaps in an existing one.

Key Takeaways

  • IT infrastructure monitoring is the continuous tracking of servers, networks, storage and applications to detect performance issues, failures and capacity limits before they affect users.
  • Monitoring and observability are related but different: monitoring tells you that something is wrong; observability helps you understand why.
  • A recent industry analysis of enterprise outage data found that a majority of outages involve failures that were technically detectable beforehand, meaning stronger monitoring could have caught many of them before they became user-facing incidents (JustAnalytics, 2026).
  • A working monitoring setup needs four things in place: a complete inventory of what’s being monitored, defined thresholds for “healthy” versus “at risk,” a clear alerting and escalation path, and dashboards that translate technical data into business-relevant reporting.
  • Uptime monitoring and SLA dashboards matter as much for accountability and stakeholder trust as they do for technical troubleshooting.

What Is IT Infrastructure Monitoring?

IT infrastructure monitoring is the ongoing practice of collecting and analyzing data from servers, network devices, storage systems, cloud resources and applications to understand whether they’re performing as expected. It covers metrics like uptime, response time, resource utilization and error rates, and it’s designed to surface problems early, ideally before they cause downtime rather than after.

This is different from a one-time health check or an annual infrastructure audit. Monitoring is continuous by definition: data is collected in near real time, compared against expected baselines, and used to trigger alerts the moment something drifts outside a normal range. Within a wider IT infrastructure management framework, monitoring is the layer that turns raw data into early warnings.

Monitoring vs. Observability: What’s the Difference?

These two terms get used interchangeably, but they answer different questions.

Monitoring tells you that something is wrong. It’s built around predefined metrics and thresholds: CPU usage crossed 90%, a server stopped responding, latency spiked above an acceptable range. Monitoring is excellent at detecting known failure patterns you’ve already anticipated and configured alerts for.

Observability goes a step further and helps you understand why something is wrong, even for problems you didn’t anticipate. It typically combines three types of data (metrics, logs and traces) so that when an alert fires, an engineer can trace the issue back through the system rather than starting an investigation from scratch.

In practice, most organizations need both. Monitoring catches the known problems and keeps day-to-day operations visible; observability becomes essential once infrastructure is complex enough (multiple cloud environments, microservices, distributed offices) that root-causing an issue requires connecting data across several systems rather than looking at one dashboard.

Key Metrics to Track

Effective infrastructure monitoring depends on tracking the right metrics, not the most metrics. A few categories consistently matter most:

Server monitoring metrics: CPU utilization, memory usage, disk I/O, and available storage capacity. These metrics catch resource exhaustion before it causes a crash or severe slowdown, and trending them over time helps with capacity planning rather than just incident response.

Network monitoring metrics: bandwidth utilization, packet loss, latency, and jitter across routers, switches and WAN links. Network issues are often the hardest to diagnose after the fact because they can be intermittent, which makes continuous monitoring more valuable here than almost anywhere else in the stack.

Uptime and availability: the percentage of time a system, service or application is available and functioning, usually tracked against an internal or contractual target (commonly expressed as “three nines,” “four nines,” and so on). Uptime monitoring is often the single metric business stakeholders care about most, even when the underlying technical picture is more nuanced.

Response time and latency: how quickly a system responds to a request. This matters for both internal systems (an ERP or file server) and customer-facing ones (a website or transaction platform), where slow performance often drives complaints before an actual outage does.

Error rates: the frequency of failed requests, transactions or processes, which often signals a developing problem well before a full outage occurs.

Security-relevant signals: unusual login patterns, unexpected configuration changes, and failed access attempts, which increasingly need to be monitored alongside performance metrics rather than as a completely separate discipline. Centralized logging is one of the twelve controls in our IT infrastructure security checklist.

How to Set Up IT Infrastructure Monitoring: A Step-by-Step Guide

Step 1: Build a Complete Inventory of What Needs Monitoring

You cannot monitor what you haven’t accounted for. Start with a full inventory of infrastructure components: servers, network devices, cloud resources, storage systems, critical applications and, where relevant, end-user devices. Many monitoring gaps trace back to this step being incomplete: a branch office switch, a legacy server, or a cloud resource spun up outside the standard process often ends up invisible until it fails.

Step 2: Define Baselines and Thresholds

For each component, decide what “normal” looks like and where the warning and critical thresholds sit. A server running at 60% CPU may be perfectly healthy; the same server sustained at 95% for an hour is a different story. Thresholds should be based on actual historical behavior wherever possible, not generic defaults, since every environment has a different normal.

Step 3: Choose the Right Monitoring Tools for Each Layer

Different layers of infrastructure typically need different tooling: network monitoring platforms, server and system monitoring agents, cloud-native monitoring services, and application performance monitoring tools. Some platforms cover multiple layers in one place; others are purpose-built for a single domain and need to be integrated together. The right choice depends on how much of the estate is on-premises versus cloud, how many locations need coverage, and how much the existing team can realistically manage day to day.

Step 4: Configure Alerting and Escalation

An alert that nobody sees, or that goes to the wrong person, is functionally the same as no monitoring at all. Set up alerting with clear severity levels, defined escalation paths, and enough context in the alert itself that whoever receives it can act quickly rather than starting an investigation from zero. Alert fatigue is a real risk here: too many low-value alerts train teams to ignore notifications altogether, which defeats the purpose of monitoring in the first place.

Step 5: Build SLA Dashboards for Stakeholders

Technical dashboards built for engineers and SLA dashboards built for business stakeholders usually need to look different. Leadership generally wants a small number of clear indicators (uptime percentage, incidents resolved within SLA, average resolution time) presented in a way that’s easy to review at a glance, without needing to interpret raw technical metrics. Building this layer on top of the technical monitoring stack turns infrastructure data into something leadership can actually use for decision-making and for holding vendors to their support SLAs.

Step 6: Review, Tune and Expand Coverage Over Time

Monitoring isn’t a one-time setup. Thresholds need periodic review as usage patterns change, new infrastructure needs to be added to coverage as it’s deployed, and alert rules need tuning as teams learn which ones are genuinely actionable versus noise. Organizations that treat monitoring as a project with an end date tend to end up with coverage that quietly goes stale within a year. Once coverage is stable, alerts can also start triggering fixes automatically, which is where IT infrastructure automation picks up.

Types of Infrastructure Monitoring Tools

Infrastructure monitoring tools generally fall into a few categories, and most mature environments end up using more than one:

  • Network monitoring tools: track the health and performance of routers, switches, firewalls and WAN links, often using protocols like SNMP to pull device-level data.
  • Server and system monitoring tools: track CPU, memory, disk and process-level health on physical and virtual servers, typically via lightweight agents installed on each system.
  • Cloud-native monitoring services: built into major cloud platforms to track the health and performance of cloud-hosted resources, often the fastest way to get baseline visibility into a cloud environment without deploying separate agents.
  • Application performance monitoring (APM) tools: track how software applications actually perform from the user’s perspective, including transaction times and error rates within the application layer itself.
  • Unified/converged monitoring platforms: aim to bring several of the categories above into a single view, reducing the number of dashboards a team needs to check, at the cost of sometimes being less deep in any one specific domain than a purpose-built tool.

No single tool category is inherently “best”. The right combination depends on the environment being monitored and how centralized the IT team wants visibility to be.

Network Monitoring in India: What’s Different

Network monitoring for enterprises with operations across India comes with a few practical wrinkles worth planning for early rather than discovering later.

Multi-location connectivity variance. Enterprises with offices across metros and smaller cities often deal with a wider spread of ISP reliability and bandwidth quality between locations than a single-city or single-country operation would. Monitoring needs to account for location-specific baselines rather than one blanket threshold applied everywhere.

Hybrid and branch office complexity. Distributed teams working across head office, branch locations and remote setups mean remote infrastructure monitoring has to cover far more edge points than a centralized office model, each with its own router, switch and connectivity profile to track.

Cost-conscious bandwidth management. Bandwidth costs and availability can vary meaningfully by location, which makes network utilization monitoring not just a performance exercise but a cost-management one: spotting unusual traffic patterns before they translate into unnecessary spend or a saturated link at a critical site.

Compliance and data residency considerations. As data protection requirements evolve, monitoring systems themselves, and where the data they collect is stored, increasingly need to be reviewed against the same compliance lens applied to the rest of the infrastructure.

None of this changes the fundamentals of monitoring covered earlier. It just means the setup needs to account for a more distributed, variable environment than monitoring a single, centralized data center would.

Common Mistakes That Undermine Monitoring Programs

A few patterns show up repeatedly in monitoring setups that don’t deliver what they should:

  • Monitoring everything at the same priority level, which buries the handful of metrics that actually matter under noise.
  • Setting thresholds once and never revisiting them, even as usage patterns and infrastructure change.
  • No clear ownership of alerts, so notifications go out but nobody is explicitly accountable for acting on them.
  • Treating uptime as the only metric that matters, while ignoring early-warning signals like rising error rates or degrading response times that typically precede an actual outage.
  • Building technical dashboards only, with no equivalent view for business stakeholders, which makes it hard to demonstrate monitoring’s value or hold vendors accountable against SLAs.

Where an Experienced Technology Partner Helps

Building and running infrastructure monitoring well requires more than installing a tool. It requires the discipline to keep thresholds current, alerts meaningful, and dashboards relevant as the environment keeps changing. For many internal IT teams, this is exactly the kind of ongoing operational work that’s hard to sustain alongside everything else on their plate, which is why many hand it to a 24×7 NOC.

This is where working with an experienced managed services partner adds value: helping design a monitoring setup that matches the actual environment, managing the day-to-day tuning that keeps alerts useful rather than noisy, and providing the SLA dashboards and reporting that give leadership real visibility into infrastructure health, not just when something breaks but as an ongoing part of how the IT environment is managed.

If your organization’s monitoring setup hasn’t been reviewed in a while, or alerts have started to feel more like noise than signal, that’s usually a sign it’s time to revisit the approach, ideally with a partner who can help build it right the first time.

Related reading

Frequently Asked Questions

What is IT infrastructure monitoring?

IT infrastructure monitoring is the continuous tracking of servers, networks, storage systems and applications to detect performance issues, failures and capacity constraints, ideally before they cause downtime or affect users.

What is the difference between monitoring and observability?

Monitoring tells you that something is wrong, based on predefined metrics and thresholds. Observability helps you understand why something is wrong, by combining metrics, logs and traces so an issue can be traced back to its root cause, including problems that weren't anticipated in advance.

What metrics should be included in server monitoring?

Core server monitoring metrics include CPU utilization, memory usage, disk I/O, available storage capacity, and process-level health. Tracking these over time supports both immediate troubleshooting and longer-term capacity planning.

What is an SLA dashboard used for?

An SLA dashboard translates technical monitoring data into business-relevant reporting, typically showing uptime percentage, incidents resolved within agreed timeframes, and average resolution time. It's built for stakeholders who need a clear view of service performance without interpreting raw technical metrics.

How is network monitoring different for enterprises with multiple locations in India?

Multi-location enterprises in India often deal with varying ISP reliability and bandwidth quality across cities, more distributed edge points to monitor across branch offices, and bandwidth costs that differ meaningfully by location. Monitoring needs location-specific baselines rather than a single threshold applied uniformly across every site.

Should infrastructure monitoring be managed in-house or outsourced?

It depends on internal team capacity and how much ongoing tuning the organization can sustain. Some enterprises manage monitoring fully in-house; many others use a managed or co-managed model, where a technology partner handles day-to-day monitoring operations while internal teams retain oversight of strategy and critical systems.

IT Infrastructure Support Services: Models, SLAs and What They Cost

When an enterprise decides it needs “better IT support,” that decision usually hides several smaller ones. Should support be handled in-house or by an external partner? Does every issue need an engineer onsite, or can most be resolved remotely? What response times actually matter, and what should they cost?

IT infrastructure support services span all of this: the people, processes and tools that keep servers, networks, devices and applications running, and the models organizations use to deliver that support. This guide compares the main models, explains how support tiers and SLAs work, and lays out what actually drives cost.

Key Takeaways

  • IT infrastructure support typically runs through a tiered L1, L2, L3 model, with each level handling a different depth of issue and a different level of technical expertise.
  • Onsite and remote support solve different problems. Most enterprises need both, not one or the other.
  • Support can be delivered in-house, fully outsourced, or through a co-managed model. Each comes with different cost, control and scalability trade-offs.
  • IT service desk SLAs are usually built around response time, resolution time and severity classification, not a single uptime number.
  • Cost is driven less by “how many devices” and more by coverage hours, SLA tightness, and whether support is delivered onsite or remotely.

What Are IT Infrastructure Support Services?

IT infrastructure support services cover the ongoing help desk, troubleshooting and technical resolution work that keeps an organization’s servers, networks, devices and core systems operational, from a user unable to log in, to a network outage affecting an entire office, to a server issue needing specialist diagnosis.

Support is often confused with infrastructure management, but the two are related, not identical. Infrastructure management is the broader, proactive discipline of planning, monitoring and maintaining infrastructure (see our guide to IT infrastructure monitoring). Support is the reactive layer within it: what happens once someone raises an issue.

The L1, L2, L3 Support Model Explained

Most IT support operations, whether in-house or outsourced, are structured around three tiers. Each tier handles a different depth of problem, and issues escalate upward when a lower tier can’t resolve them.

Support Tier Typical Scope Example Issues Skill Level
L1 (First-Line) Initial triage, basic troubleshooting, ticket logging Password resets, printer connectivity, basic application errors General IT support skills
L2 (Second-Line) Deeper technical troubleshooting, configuration issues Network connectivity problems, software installation conflicts, device-specific hardware faults Specialized technical knowledge
L3 (Third-Line) Complex, specialist-level resolution Server infrastructure failures, deep application or system-level bugs, root-cause analysis for recurring issues Expert or vendor-level expertise

This structure matters because it directly affects resolution speed and how efficiently support resources get used. A strong L1 desk resolves most tickets without ever escalating, freeing L2 and L3 specialists for genuinely complex problems. When L1 lacks the training or authority to close simple issues, everything backs up into higher tiers and resolution times slow across the board.

Onsite vs Remote IT Support: Which Do You Need?

Not every issue can be solved over a call, and not every issue needs someone physically present. Understanding the difference helps set realistic expectations for both cost and speed.

Factor Onsite Support Remote Support
Best for Hardware failures, physical setup, network cabling issues, device deployment Software issues, configuration changes, most user-reported tickets
Speed Slower, dependent on travel time and technician availability Faster, often resolved within minutes to hours
Cost Generally higher due to travel and technician time onsite Generally lower, since one technician can support many locations
Coverage limitations Limited by geography and technician availability Limited by what can actually be diagnosed and fixed without physical access
Typical use case New device rollouts, server room issues, network hardware faults Password resets, application troubleshooting, most day-to-day tickets

In practice, most support tickets can be resolved remotely. Onsite support becomes necessary for a smaller set of issues: physical hardware failures, new equipment deployment, or cases where remote diagnosis genuinely can’t reach the root cause. Organizations that build support around remote-first resolution, with onsite reserved for what actually needs it, typically get faster average resolution times without losing coverage where a technician is truly required.

Support Delivery Models Compared

Beyond tiers and location, there’s the question of who actually delivers the support. Three models cover most enterprise setups. If you are weighing an AMC or staff augmentation instead, see IT AMC vs managed services vs staff augmentation.

Model How It Works Best For Trade-offs
In-House Internal IT team handles all support tiers directly Organizations with highly specialized or sensitive internal systems, and the budget to staff around the clock Requires sustained investment in staffing, training and technology across every tier
Fully Outsourced An external partner manages the entire support function, from L1 through L3, under a defined SLA Organizations wanting predictable costs and 24×7 coverage without building it internally Less direct day-to-day control over how support staff are managed
Co-Managed Internal team retains L1 or specific systems; a partner handles overflow, after-hours coverage or specialist tiers Mid-to-large enterprises that want to keep core knowledge in-house while extending coverage and capacity Requires clear division of responsibility to avoid gaps or duplicated effort

There isn’t a universally correct choice here. An organization with a small, specialized internal team might keep L1 in-house, where institutional knowledge matters most, while outsourcing after-hours and L2/L3 coverage to a partner who can staff it more cost-effectively. A larger enterprise juggling multiple locations may find a fully managed model simpler to govern than coordinating several internal shifts across time zones.

24×7 IT Support in India: What It Actually Requires

Round-the-clock support sounds straightforward on paper, but delivering it well involves more moving parts than most organizations budget for.

Shift staffing, not just extended hours. True 24×7 coverage means at least three staffed shifts, not one team working longer hours. Skipping this usually shows up as slower response times overnight, even when a desk is technically “open.”

Multi-location coordination. Enterprises with offices across several Indian cities, or with international operations, often need coverage that accounts for different working hours, network conditions, and sometimes regulatory requirements per location.

Escalation paths that work at 2 a.m. A tiered model only works if L2 and L3 specialists are genuinely reachable off-hours, not just theoretically on-call. Escalation paths that look fine on paper often break down in practice if the people behind them aren’t set up to respond quickly at odd hours.

Consistent quality across shifts. Night and weekend coverage sometimes gets treated as lower priority, showing up as longer resolution times during off-hours. A well-run 24×7 operation holds the same quality bar across every shift.

Organizations evaluating 24×7 support, in-house or from an IT infrastructure services company, should ask specifically how staffing and quality are handled outside standard hours, not just whether the phone line is technically answered around the clock.

Understanding IT Service Desk SLAs

An SLA (service level agreement) for IT support is usually built around three components, not a single number.

  • Response time: how quickly an issue is acknowledged after it’s reported.
  • Resolution time: how quickly it’s actually fixed.
  • Severity classification: how urgently different types of issues are treated.
Severity Level Example Issue Typical Response Expectation Typical Resolution Expectation
Critical (P1) Full system or network outage affecting multiple users Within minutes Fastest possible, often measured in hours
High (P2) Major functionality impaired, affecting a team or department Within an hour or two Same business day
Medium (P3) Individual user issue with a workaround available Within a few hours Within one to two business days
Low (P4) Minor issue, cosmetic or non-urgent request Within one business day As scheduled, no immediate urgency

These timeframes vary meaningfully between organizations and providers, and the table above reflects common structuring rather than a fixed standard. What matters more than the exact numbers is whether severity levels are clearly defined, consistently applied, and reported on regularly, so an SLA becomes something you can actually hold a support provider accountable to, rather than a document that only gets reviewed after something goes wrong. Some organizations now go a step further and add experience level agreements (XLAs) on top of SLAs.

What Does IT Infrastructure Support Actually Cost?

There’s no single number here, because cost depends heavily on scope. A few factors drive price more than headcount or device count alone:

Coverage hours. Business-hours-only support costs meaningfully less than genuine 24×7 coverage, which requires multiple staffed shifts rather than extended hours from one team.

SLA tightness. Faster guaranteed response and resolution times require more available capacity on standby, which costs more than looser SLAs.

Onsite requirement. Support that includes regular onsite visits costs more than remote-only support, since travel time and technician availability both factor into pricing.

Support tier depth. A contract covering only L1 triage costs less than one including L2 and L3 specialist coverage, since deeper expertise commands a higher rate.

Number of locations and users. More locations generally mean more coordination complexity, even when total user count is similar to a single-site deployment.

Bundled vs. per-incident pricing. Some organizations prefer a flat monthly cost covering unlimited support within scope; others prefer per-incident pricing, which can be cheaper for low-volume needs but less predictable at scale.

Rather than asking “what does IT support cost,” a more useful question is “what combination of coverage hours, SLA commitments and support depth do we actually need,” since that combination is what determines the price a provider will quote.

How to Choose the Right Support Model

A few questions help narrow the decision:

  1. How much of your support volume genuinely needs deep technical expertise? If most tickets are routine, a strong L1 desk, whether in-house or outsourced, solves most of the problem on its own.
  2. Do you need coverage outside standard business hours? If yes, weigh the cost of building genuine 24×7 shift coverage internally against a partner who already has it staffed.
  3. How distributed is your organization? Multiple locations usually favor a model with strong remote-first resolution and clearly defined onsite escalation, rather than relying on a single central team to physically reach every site.
  4. Can you hold your current SLA accountable? If severity levels aren’t clearly defined or reported on, that’s worth fixing before evaluating whether the underlying support model itself needs to change.

Where Team Computers Fits In

Team Computers works with enterprises to design and deliver IT infrastructure support that matches how the organization actually operates, rather than a generic one-size package. That includes structuring the right mix of L1, L2 and L3 coverage, balancing onsite and remote resolution based on real ticket patterns, and building SLAs with clear severity definitions and reporting leadership can actually use.

For organizations managing enterprise Windows devices and workplace technology, support is only as good as its connection to the broader device lifecycle. A desk that knows a device’s deployment history, warranty status and refresh timeline resolves issues faster than one working from a ticket alone. This is where a single technology partner across procurement, deployment and support changes the experience for both the IT team and the employees relying on their devices daily.

If your current support model isn’t giving you clear visibility into response times, resolution rates or where issues are actually coming from, that’s a good starting point for a conversation about what a better-fitted model would look like.

Related reading

Frequently Asked Questions

What is the difference between L1, L2 and L3 IT support?

L1 handles first-line triage and basic troubleshooting, such as password resets or simple application errors. L2 handles deeper technical issues that require more specialized knowledge, such as network configuration problems. L3 handles complex, specialist-level issues, including root-cause analysis for recurring or infrastructure-level problems.

Is onsite or remote IT support better?

Neither is universally better. Most day-to-day issues, especially software and configuration problems, can be resolved remotely and faster than waiting for onsite support. Physical hardware failures and new device deployments genuinely require someone onsite. Most enterprises need a combination of both.

What should an IT service desk SLA include?

A well-structured SLA defines response time and resolution time for each severity level, from critical outages to low-priority requests, along with clear criteria for how severity is classified, plus regular reporting so performance can actually be reviewed and held accountable.

How much does IT infrastructure support cost?

Cost depends primarily on coverage hours, how tight the SLA commitments are, whether onsite support is included, and how deep the support tiers need to go, rather than simply the number of devices or users covered. Business-hours-only, remote-first support with looser SLAs generally costs less than genuine 24x7 coverage with tight response times.

What does 24x7 IT support actually require to work well?

Genuine 24x7 support requires multiple staffed shifts, not just extended hours from a single team, along with escalation paths that function reliably during off-hours and the same quality standard across night, weekend and holiday coverage as during regular business hours.

IT Infrastructure Management: Framework, Tools and Service Models

Most enterprises don’t struggle with IT infrastructure because they lack technology. They struggle because the technology they already own (servers, networks, cloud accounts, laptops, security tools) isn’t managed as a connected system. Devices get provisioned by one team, patched by another, and replaced only when something breaks. Cloud spend grows without anyone tracking utilization. Network changes happen without a documented rollback plan.

This is the gap that IT infrastructure management is meant to close: a structured, ongoing discipline for planning, deploying, monitoring, securing and refreshing every technology asset an organization depends on, rather than treating each piece in isolation.

This guide covers the framework behind effective IT infrastructure management, the tools that support it, and the service models (in-house, fully outsourced, co-managed and hybrid) that Indian enterprises are choosing between in 2026. It’s written for CIOs, IT heads, procurement leaders and anyone deciding how their organization should manage the infrastructure it runs on.

Key Takeaways

  • IT infrastructure management spans four domains (network, compute/storage, cloud and end-user devices), governed by a common framework of people, process, technology and continuous improvement.
  • ITIL/ITSM remains the most widely adopted best-practice framework for structuring IT infrastructure operations, though most 2026 implementations extend it with automation and AI-driven monitoring.
  • The global managed IT infrastructure services market was valued at roughly USD 128.5 billion in 2025 and is projected to reach USD 217.7 billion by 2031, reflecting how many enterprises are shifting parts of infrastructure management to external partners (Mordor Intelligence, 2026).
  • There is no single “right” service model. Most mature enterprises now run a hybrid mix of in-house oversight and managed services rather than choosing one extreme.
  • Evaluating a partner matters as much as evaluating the technology: procurement, deployment, lifecycle management and support all need to work together, not just the initial purchase.

What Is IT Infrastructure Management?

IT infrastructure management is the ongoing practice of planning, provisioning, monitoring, securing, maintaining and eventually retiring the technology components an organization relies on to operate: networks, servers and data center resources, cloud and hybrid environments, storage and backup systems, and end-user devices such as laptops, desktops and collaboration hardware.

It is broader than “IT support.” Support is typically reactive: someone raises a ticket, and the issue gets resolved. Infrastructure management is proactive and continuous: it includes capacity planning, patch and update cycles, performance monitoring, security posture management, asset lifecycle tracking, vendor coordination and budgeting for refresh cycles, all before something breaks.

A useful way to think about it: IT infrastructure management is the discipline that keeps every layer of technology reliable, secure, and aligned to what the business actually needs, not just today but across the multi-year lifecycle of every asset.

The Core Framework: People, Process, Technology and Governance

Most mature IT infrastructure management programs, regardless of industry or company size, are built around four connected pillars.

1. People and Ownership

Clear ownership matters more than headcount. Someone needs to own network uptime, someone needs to own the endpoint fleet, and someone needs to own the relationship with each OEM or vendor. In smaller IT teams, one person may hold several of these roles; in larger enterprises, they map to dedicated functions. Ambiguous ownership is one of the most common reasons infrastructure problems go unresolved for weeks rather than hours.

2. Process: ITIL and ITSM as the Common Language

The Information Technology Infrastructure Library (ITIL) remains the most widely referenced framework for structuring how IT services and infrastructure are managed. It provides a shared vocabulary (incidents, problems, changes, configuration items) and a structured way to handle each of them consistently. It’s worth being precise about terminology here: ITSM (IT Service Management) describes the overall practice of managing IT services, while ITIL is one specific, globally adopted framework organizations use to run ITSM.

ITIL 4, the current version of the framework, organizes this around a Service Value System that includes guiding principles, governance, a set of management practices, and a continual improvement loop. In practice, this means infrastructure management isn’t a one-time project. It’s a cycle: plan, deploy, monitor, review, improve, repeat.

3. Technology: Visibility Before Automation

You cannot manage what you cannot see. A configuration management database (CMDB), a structured record of every asset, its owner, its dependencies and its status, is the technical foundation most frameworks are built on. In practice, a common and often underestimated problem shows up here: many enterprise environments carry a meaningful “shadow asset” gap, meaning devices, virtual machines and cloud resources that were never properly recorded in the asset inventory. Discovery scans that reconcile the real environment against the recorded one are one of the fastest ways to close that gap before it becomes an incident or an audit finding.

4. Governance and Continuous Improvement

Governance ties the other three together: documented policies for change management, security baselines, compliance requirements, and a regular cadence for reviewing whether the infrastructure is still serving business needs, or has quietly drifted out of alignment with them.

The Domains a Complete Framework Has to Cover

“IT infrastructure” is often used loosely, so it helps to be clear about what IT infrastructure actually includes. A complete management framework has to account for each of the following domains, even if a single team or partner doesn’t own all of them:

  • Network infrastructure: routers, switches, firewalls, SD-WAN, wireless access, and the connectivity that ties every location and user together.
  • Servers and data center resources: physical and virtualized compute, whether on-premises, colocated, or cloud-hosted.
  • Cloud and hybrid environments: public cloud accounts, hybrid workloads, and the governance needed to prevent cost sprawl and configuration drift. Most enterprises today operate hybrid and multi-cloud environments by design rather than as a transitional phase, which raises the bar for consistent visibility and governance across environments.
  • Storage and backup: data availability, retention policies, and disaster recovery readiness.
  • Security infrastructure: endpoint protection, identity and access management, monitoring, and incident response capability layered across every domain above. Our IT infrastructure security checklist covers the twelve controls worth reviewing.
  • End-user computing and devices: the laptops, desktops, and collaboration hardware employees actually use every day. This domain is frequently under-managed relative to its size: enterprises invest heavily in data center and cloud governance while device procurement, deployment and refresh planning remain fragmented across separate purchase orders and IT tickets.

That last point matters more than it might initially seem. A network can be perfectly optimized and a data center perfectly governed, but if devices are procured ad hoc, deployed without a standard image, and kept in service well past their useful life, the organization still experiences the practical symptoms of poor infrastructure management: higher support costs, security gaps, and inconsistent employee experience.

Tools That Power Modern IT Infrastructure Management

The tooling layer has shifted substantially over the past two years, largely driven by the volume of infrastructure most enterprises now run. A few categories now show up consistently in mature environments:

Monitoring and observability platforms track the health, performance and availability of infrastructure components in real time, replacing the older model of dashboards reviewed periodically with continuous, outcome-linked tracking tied to service-level objectives. Our IT infrastructure monitoring guide covers the metrics and setup steps in detail.

ITSM and ITAM platforms manage the ticketing, change approval and asset-tracking workflows that ITIL processes are built around. They are the operational backbone for incident, problem and change management.

Unified endpoint management (UEM) and remote monitoring and management (RMM) tools give IT teams visibility and control over laptops, desktops and mobile devices at scale: patching, configuration enforcement and remote troubleshooting, without a technician physically present at every device.

AIOps and automation platforms are the newest addition to this stack. Industry forecasts suggest a large share of large organizations will lean on AI-driven monitoring to manage IT performance proactively within the next year or two, and deployments that pair centralized management with AIOps have reported measurable efficiency gains. The caveat worth taking seriously: these systems are only as reliable as the asset and configuration data feeding them. An automation layer built on an inaccurate CMDB doesn’t fix data quality problems. It acts on them at machine speed, which is why IT infrastructure automation works best when it starts with the basics.

Security and identity tools (endpoint detection and response, access management and vulnerability scanning) increasingly need to integrate with the monitoring and ITSM layers rather than operate as a separate silo.

No single tool covers every domain, and tool sprawl is itself a recognized risk. Fragmented tooling across hybrid environments is increasingly seen as unsustainable, pushing organizations toward more standardized, centrally governed toolsets.

IT Infrastructure Management Service Models

Once the framework and tooling are clear, the remaining decision is who actually runs it day to day. Broadly, enterprises choose between four models, and increasingly a blend of more than one.

1. Fully In-House

The internal IT team owns every domain: procurement, deployment, monitoring, security and support. This model offers maximum control and institutional knowledge but requires sustained investment in staffing, training and tooling across every infrastructure domain. Network, cloud, endpoint and security specialists all need to be maintained in-house, which becomes harder to justify as environments grow more complex.

2. Fully Managed (IT Infrastructure Managed Services)

An external partner takes end-to-end responsibility for some or all infrastructure domains, commonly described as IT infrastructure managed services or managed IT infrastructure services. The organization gets predictable costs, 24/7 coverage, and access to specialized expertise it would be expensive to build internally. The trade-off is less direct day-to-day control, which is why most enterprises apply this model selectively rather than universally: for example, outsourcing device lifecycle and network operations while retaining in-house ownership of core applications and data governance.

3. Co-Managed / Hybrid

The internal team retains ownership of strategy, security policy and business-critical systems, while a partner handles defined operational domains such as device deployment and refresh, help desk escalation, network monitoring, or specific projects like a Windows migration. This model has become the most common pattern among mid-to-large enterprises because it combines internal institutional knowledge with external scale and specialization, without requiring an all-or-nothing commitment.

4. Staff Augmentation and Project-Based Engagement

A partner supplies specialized skills or additional capacity for a defined period (a data center migration, a large-scale device refresh or a security audit) without an ongoing management relationship. Useful for one-time initiatives, less suited to continuous infrastructure operations. For how this compares with an AMC or a managed services contract, see IT AMC vs managed services vs staff augmentation.

Which Model Fits?

The right model usually depends on three factors: how specialized the domain is relative to the internal team’s existing skills, how much predictability the organization needs in its IT spend, and how much of IT leadership’s time should go toward strategic work versus operational firefighting. A useful diagnostic question for any CIO: if the internal team disappeared tomorrow, which infrastructure domains would the organization struggle to keep running? Those are usually the domains best suited to a managed or co-managed model.

Why the Shift Toward Managed IT Infrastructure Services Is Accelerating

The market data reflects a clear directional shift. The global managed IT infrastructure services market was valued at roughly USD 128.5 billion in 2025 and is projected to grow to about USD 217.7 billion by 2031, a compound annual growth rate of approximately 9.2% (Mordor Intelligence, 2026). Cloud-based deployment already represents the majority of that market, though hybrid approaches are forecast to grow faster than cloud-only deployments over the next several years, a signal that most enterprises aren’t choosing between on-premises and cloud, but managing both together.

India’s position within this shift is notable. The domestic managed services market has moved from India primarily exporting IT management expertise to also becoming one of the fastest-growing consumption markets globally, driven by digital transformation programs across BFSI, manufacturing, healthcare and government sectors. India is widely expected to be among the fastest-growing markets globally for managed IT infrastructure services through the early 2030s.

A few forces are consistently cited behind this shift:

  • Rising complexity. Hybrid and multi-cloud environments, distributed workforces and expanding device fleets are harder to manage with static, in-house-only teams.
  • Security and compliance pressure. Regulatory and data-sovereignty requirements are tightening in multiple regions, and organizations increasingly want infrastructure partners who can demonstrate structured security practices, not just uptime.
  • Cost predictability. Managed models convert unpredictable capital and staffing costs into more predictable operating costs, which matters more as IT budgets face closer scrutiny.
  • Focus on core business. IT leadership increasingly wants to spend less time on operational firefighting and more time on initiatives that are directly tied to business outcomes.

None of this means every organization should outsource everything. It does mean that treating infrastructure management as a purely internal, static function is increasingly out of step with how mature enterprises are actually operating.

Where End-User Devices Fit Into the Bigger Picture

Of the domains covered earlier, end-user devices deserve specific attention because they are the part of infrastructure every employee interacts with daily, and the part most often managed as a series of disconnected purchase decisions rather than a lifecycle.

A well-run device fleet touches nearly every framework element discussed above: it needs to be discovered and tracked (asset visibility), provisioned consistently (process), monitored and patched (technology and security), and refreshed on a planned cycle rather than reactively (governance). Getting this right requires evaluating requirements across multiple OEM options, since devices from Dell, HP, Lenovo, ASUS, Acer, Microsoft Surface and Logitech collaboration hardware each suit different roles, budgets and use cases. It also means deploying at scale without disrupting operations, and managing the fleet through its full lifecycle, including secure end-of-life disposal.

This is also where the gap between “buying technology” and “managing infrastructure” becomes most visible. Standardizing on the wrong device mix, skipping a structured deployment process, or letting refresh cycles slip past their useful window all create the same downstream symptoms as poor network or cloud governance: higher support costs, security exposure and inconsistent user experience, just at the endpoint layer instead of the data center.

How to Evaluate an IT Infrastructure Management Partner

Whether an organization is choosing a fully managed provider or a co-managed partner for specific domains, a few evaluation criteria consistently separate a good fit from a mismatched one:

  1. Does the partner work advisory-first, or transaction-first? A partner who starts by understanding requirements and recommending the right fit, across multiple OEM options where relevant, is different from one who leads with a product catalog.
  2. Can they support the full lifecycle, not just the initial deployment? Procurement, deployment, ongoing management, refresh planning and end-of-life disposal should be part of one coordinated relationship, not five separate vendor conversations.
  3. Do they offer a single point of contact across domains? Fragmented ownership between network, endpoint and security vendors recreates the exact coordination problem infrastructure management is meant to solve.
  4. Is their process documented and auditable? Structured change management, incident handling and reporting should be visible, not something you discover only when something goes wrong.
  5. Can they flex across environments? Hybrid infrastructure requires a partner comfortable working across on-premises, cloud and multi-vendor device environments, not one tied to a single platform or OEM.

For the full list of questions to ask and red flags to watch for, see how to choose an IT infrastructure services company in India.

Where Team Computers Fits In

Team Computers works with enterprises as a technology partner across IT infrastructure solutions, with particular depth in enterprise Windows devices and workplace technology. That means helping organizations evaluate requirements, select the right mix across OEM partners like Dell, HP, Lenovo, ASUS, Acer, Microsoft Surface and Logitech, and manage that technology through deployment, support, refresh and end-of-life stages.

The role isn’t to replace the framework discussed above. It’s to help execute it. Choosing devices is only one decision inside a much larger infrastructure management lifecycle: organizations still need to plan deployment at scale, keep fleets supported and secure, plan refresh cycles before aging devices become a liability, and manage disposal responsibly. This is where having an experienced technology partner involved changes the equation, giving IT leadership a single point of contact for enterprise device strategy rather than a series of disconnected purchase decisions.

If your organization is reassessing how its device fleet and broader endpoint strategy fit into its IT infrastructure management approach, that’s a conversation worth having before the next procurement or refresh cycle begins.

Related reading

Frequently Asked Questions

What is the difference between IT infrastructure management and IT support?

IT support is typically reactive: it resolves issues as they're reported. IT infrastructure management is proactive and continuous, covering planning, monitoring, security, lifecycle management and governance across every infrastructure domain, with support as one component rather than the whole function.

What is the ITIL framework used for?

ITIL (Information Technology Infrastructure Library) is a widely adopted framework of best practices for IT service management. It gives organizations a structured, common vocabulary (incidents, problems, changes, configuration items) for managing IT services and infrastructure consistently, and it underpins how most enterprise ITSM programs are organized today.

What are IT infrastructure managed services?

IT infrastructure managed services refer to an arrangement where an external partner takes ongoing responsibility for managing some or all of an organization's infrastructure (network, servers, cloud, endpoints or security), typically under a defined scope and service-level agreement, rather than the organization managing everything with an internal team alone.

Should a mid-sized enterprise fully outsource IT infrastructure management?

Not necessarily. Most mid-sized and large enterprises use a co-managed model, retaining internal ownership of strategy and core systems while a partner handles specific domains like device lifecycle, network monitoring or help desk escalation. The right split depends on internal team capacity, how specialized each domain is, and how much budget predictability the organization needs.

How often should enterprise devices be refreshed as part of an infrastructure management plan?

Refresh timing varies by device type, usage intensity and organizational risk tolerance, and should be planned as part of a documented lifecycle policy rather than decided device-by-device. A structured device lifecycle plan, developed with input from an experienced technology partner, helps organizations time refreshes before performance, support cost, and security risk start working against them.

India’s Digital Transformation Journey over the last 75 years

The Indian government’s 1950 strategy was a very particular one, broadly aiming at rapid industrialisation abiding by the centrally aligned five-year-plans. However over the years, enterprises realised that mere industrialisation was not enough, there was a need to configure ways of “smart industrialisation” where in the picture came the need to make some concrete digital moves.

Prior to 1980 the Indian IT market was all about hardware products and the software industry literally did not exist. With some significant changes in the Indian economy, including trade liberalisation and relaxation in entry barriers; softwares came into existence in the country after the 90’s. Coming a long way in our Digital journey, starting from “smart industries” we are now deriving ways to establish “smart cities” leveraging technologies like Automation, IoT and Artificial Intelligence.

Trends that initiated India’s Digital way forward 

#trend1 The desire of replacing manpower with “smart” power

A majority of Indian workforce was busy doing repetitive tasks that required no human judgment and critical thinking, reducing their levels of productivity and quality of decisions. Sooner or later the people of India realised that they need to replace human labor with smart machines, robots and other forms of automation in order to carry out the routine, repetitive back-office tasks. Thus pushing people to look for digital, automation solutions.

#trend2 The mission of becoming a “paperless, faceless, cashless” economy

the strengthening of the country’s Digital Payment Infrastructure and give every citizen a fixed India initiated the programme “Digital India” in 2015 as a way to push the country’s digital transformation forward and empower citizens in the process. The initiative was to work towards and secure digital identity. Various forms of promotions initiated by the government pushed citizens to feel digitally empowered and go cashless, bringing a boom of fin-tech startups.

#trend3 The vision of selling an “experience” not just a product or service 

Taking a lesson from global competitors, Indian entrepreneurs realised how important it was to sell an experience and not just a product or service in order to survive and succeed all together in the competitive market. There came a need for enterprises to look for solutions that provide quality customer experience, before and after availing a service or buying a product; opening doors for all kinds of application solutions.

We’ve come a long way! 

India’s digital journey has had its fair share of hiccups, along with ever changing needs of the indian consumers and the process flows of indian organisations, both public and private; it took us more than seven decades to call ourselves a “Digital Economy”. Today, India ranks third amongst the most attractive destinations for technology investments in the world. From Pharma to manufacturing to automobile, every sector has been working aggressively towards establishing the country as a leader in industrialisation and technological development.

We are there to help you kickstart your digital transformation journey, today!

Let’s connect over a cup of coffee?

https://www.teamcomputers.com/

India’s Second Google Cloud Region is now Live in Delhi NCR

Big news for India as Google launches their second cloud region in Delhi NCR. Check out how Indian businesses will benefit from it!

15th July 2021 will be remembered as an important event for Indian businesses in their journey towards digital transformation in India. Google India has launched its second region in Delhi NCR after launching it, for the first time, in 2017, in Mumbai. This new addition has made it rank 26th globally and 10th in the Asia Pacific region.

According to Thomas Kurian, Chief Executive Officer, Google Cloud, the rationale behind this decision is enormous growth in demand for capacity building, low latency, and the need for disaster recovery solutions in India. He said  “India is one of our fastest growing markets.”

The decision helps in pursuing the policy of data localization and requires a long-term commitment in terms of capital and infrastructure investment on behalf of Google India to tap the opportunities arising from existing and new customers. The new region of Delhi NCR will help the businesses to take advantage of infrastructure services and big data that are in alignment with India’s data laws and regulations.

Google Cloud resources are hosted at multiple locations across the globe at global, regional, and zonal levels. The two cloud regions deployed in India are for Google Cloud Platform resources comprising three or more zones each having a single failure domain in the region. The new region of Delhi NCR is dedicated to providing services and products for GCP customers and is of great importance for industries like healthcare, education, banking services, and other Public Sector Undertakings.

How will this Benefit Google India and their Customers?

In this Region, via high-performance networks, there are provisions made to protect the customers from service disruptions and to ensure delivery of a portfolio of key products like Compute Engine and BigQuery. All this will help Google India –

  • in creating a differentiated value proposition for regulated industries with enhanced disaster recovery solutions.
  • in prioritizing plans for providing various India-specific disaster recovery solutions and greater control of data,
  • in promoting transparency by investing in data privacy and security, and
  • in facilitating the organization’s smooth transition to cloud-based technology in an efficient and sustainable manner.

As per the recent report of International Data Corporation, India spent $3.6billion on public cloud services in the year 2020. The pandemic has accelerated this process by forcing companies to provide “work from home” choices to their employees in order to stop the disruptions in the working of the organizations. This resulted in a steep increase in revenue from cloud-based infrastructure and it amounted to $1.9 billion in the second half of 2020. Keeping this trend in mind, it is expected that by 2025 it will grow at a compound annual growth rate of 21.5% and will reach $9.5 billion.

Competition scenario

The biggest competitors of Google GCP are Microsoft Azure and Amazon AWS. The former entered the Indian market in 2015 and announced three Indian regions in central (Pune), West (Mumbai), and South (Chennai) India.
With the availability of more local zones, Microsoft provides data residency, within the country data replication for back-up and recovery, lower latency, and reduced network distance to its customers who can get access to private connections to the cloud.

Amazon AWS, which launched its first regional zone in 2016, is also catching up by announcing its plan to open its second AWS in Hyderabad and also is building the infrastructure of three availability zones by investing $2.8 billion in India.

While these two companies have greater regional coverage and huge infrastructure, Google is closely associated with the public sector and is empaneled as a full-service provider to central and state government agencies.

Is your phone Pegasus Free?

Well the most trending topic these days is Pegasus! With so many News Channels and these news doing rounds, Pegasus is the most searched topic and the trending one.

Spyware is a malicious software designed to enter your computer device/phones etc, to gather data about you, and forward it to a third-party (servers) without your consent secretly. You will not even come to know how, when, from where this got installed in your devices and since when your data is being under surveillance of third parties. The data could be anything that can be accessed through your device, calls, camera, location, social media surfing everything.

It  affects your network and device performance, slowing down daily user activities, which goes unnoticed.

Pegasus was also a spyware designed by an Israel based organisation to keep a check on spurious activities if any going on around. But here in India it was misused.

Now, How to know If your phone has any such spyware installed without your consent.

Well, such softwares is still being developed, but to a basic level, keep check on your history of surfing, keep an eye on URLs, a minute difference in known URLs can also be a point to raise alarm.

Your device showing up some weird behavior should also be flagged immediately. Check for MSCONFIG, Temp Folder and Install any anti malware to do a scanning.

The best way to check for spyware is by scanning your device with anti malware software. The software deep scans your hard drive to detect and remove any threat lurking in the computer.

To keep yourself protected:

  • Stay away from lucrative links/URLs
  • Never go for free softwares, keep a check on the software copies, number of downloads, spellings etc.
  • download an anti spyware browser extension
  • always be careful of giving acceptance to any cookies.

You never know! It might cost you!

For protecting your Phones from such spywares:

  • Stay away from unofficial app stores
  • Stay away from unknown links/URLs sent over whatsapp, messages etc, adhere from clicking them
  • Critically examine before giving consent to any downloads, be it cookies consent.
  • Always keep your phone/softwares updated with the latest versions.

For Protecting your computers from such spywares:

  • Avoid clicking on email links or attachments, until you are confident enough
  • Use Pop Up Blockers for browsers
  • Use runtime application software to keep a list of preapproved links.

Even the safest of the safe and secured iOS and androids can also be attacked So Stay Alert

Protecting your data and identity needs to be your top priority, and it simply can’t be done through understanding the problem alone. Get yourself introduced to the best Information Security Expert practices and advice to help you protect yourself from potential spyware attacks with Team Computers. Think Security, Think Team.

YOUR PRIVACY, OUR PRIORITY.

https://forms.gle/QSjvDcsDrHQ36bxu7